Threefold Encoder Interaction: Hierarchical Multi-Grained Semantic Alignment for Cross-Modal Food Retrieval
Qi Wang , Dong Wang , Weidong Min , Di Gai , Qing Han , Cheng Zha , Yuling Zhong
Published In
IEEE Transactions on Multimedia (TMM)
Accepted Date
February 18, 2025
Venue Type
Journal
Venue Level
CCF-A
Publication Date
Volume
27
Pages
2848-2862
Abstract
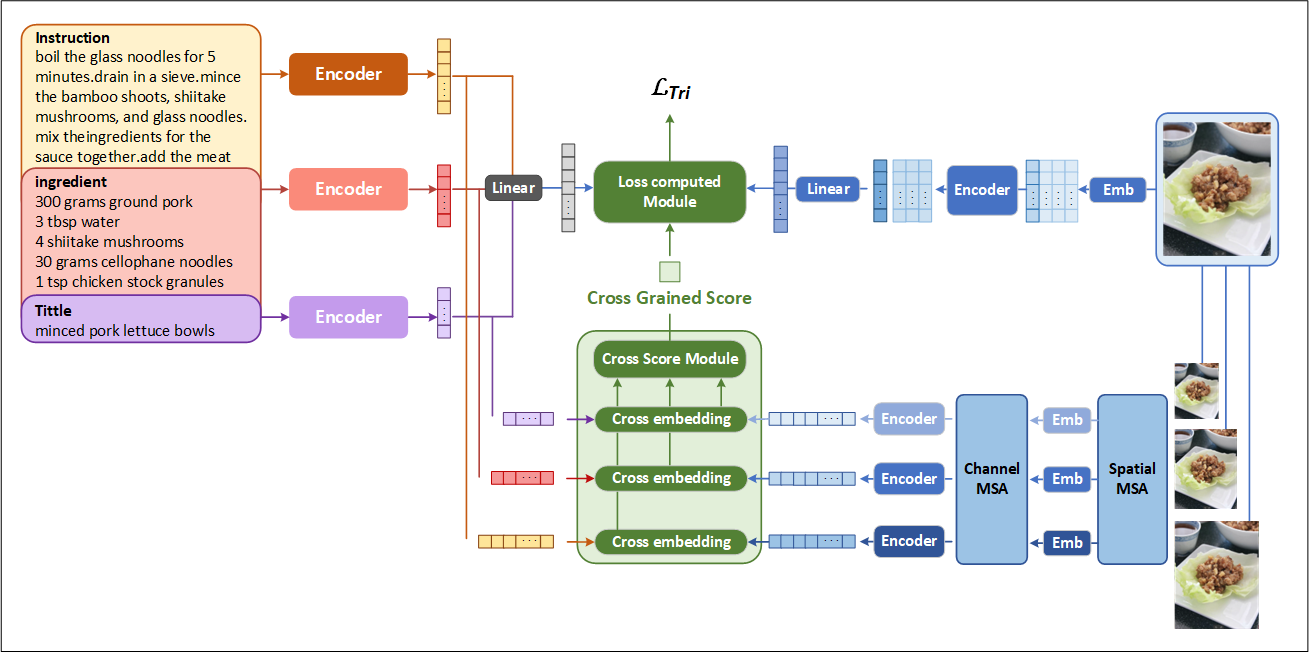
Current cross-modal food retrieval approaches focus mainly on the global visual appearance of food without explicitly considering multi-grained information. Additionally, direct calculation of the global similarity of image-recipe pairs is not particularly effective in terms of latent alignment, which suffers from mismatch during the mutual image-recipe retrieval process. This paper proposes a threefold encoder interaction (TEI) cross-modal food retrieval framework to maintain the multi-granularity of food images and the multi-levels of textual recipes to address the aforementioned challenges. The TEI framework comprises an image encoder, a recipe encoder, and a multi-grained interaction encoder. We simultaneously propose a multi-grained relation-aware attention (MRA) embedded in the multi-grained interaction encoder to capture multi-grained food visual features. The multi-grained interaction similarity scores are calculated to better establish the multi-grained correlation between recipe and image entities based on the extracted hierarchical textual and multi-grained visual features. Finally, a hierarchical multi-grained semantic alignment loss is designed to supervise the whole process of cross-modal training using the multi-grained interaction similarity scores. Extensive qualitative and quantitative experiments on the Recipe1M dataset have demonstrated that the proposed TEI framework achieves multi-grained semantic alignment between image and text modalities and is superior to other state-of-the-art methods in cross-modal food retrieval tasks.
PDF access is provided by the publisher and may require an institutional subscription or purchase.
BibTeX
@article{Wang2025ThreefoldEncoderInteraction,
  author = {Wang, Qi and Wang, Dong and Min, Weidong and Gai, Di and Han, Qing and Zha, Cheng and Zhong, Yuling},
  title = {{Threefold Encoder Interaction: Hierarchical Multi-Grained Semantic Alignment for Cross-Modal Food Retrieval}},
  journal = {IEEE Transactions on Multimedia},
  year = {2025},
  volume = {27},
  pages = {2848--2862},
  publisher = {Institute of Electrical and Electronics Engineers (IEEE)},
  doi = {10.1109/TMM.2025.3543067},
  url = {https://doi.org/10.1109/TMM.2025.3543067}
}